SFC (SolidFire Collector) 2.1
Introduction
tldr;
- My SolidFire metrics collector, SFC, was posted to Github last year. v2 was a complete rewrite; I changed back-end to InfluxDB 1, made performance improvements so that it could scale to mid-sized clusters (or better), and eliminated SolidFire SDK
- As I've blogged at the time, before, and after, I liked InfluxDB 1 (didn't want to touch version 2 with its weird SQL dialect). InfluxDB 1 was old-ish, but we already knew (from Influx Data cloud features) that version 3 was going to be great
Things turned out just as expected (if not better) as I wrote here in a post on InfluxDB 3 Alpha back in January.
I'd been busy and didn't find time to work on it (the other reason being I've never heard of a single person who uses the damn thing), but this month InfluxDB released 3.1 and 3.2 is well on its way.
With 3.2 (supposedly later this month) we may also get retention and down-sampling (which I didn't even try to implement in SFC v2.0 because in InfluxDB 1, it wasn't developer- or user-friendly at all).
With InfluxDB 3.2 coming there isn't much else to wait on:
- Excellent performance - available in 3.0
- Excellent storage efficiency - available in 3.0
- S3 tiering - available in 3.0
- Good developer tools and docs - available in 3.1
- Official UI - available in 3.1 (I haven't used it, but it's a great new improvement for users who like the UI)
- Retention management - 3.2 (?)
- RBAC - 3.2 (?) - not really necessary in SFC, but it would enable multi-tenancy for SolidFire users with many clusters
So I've started working on updating SFC for Influx DB 3.
SFC 2.1
The SFC v2.0.0 post has (slightly) better screenshots, as does the Github repository, but the point is: SFC is storing metrics in InfluxDB 3.
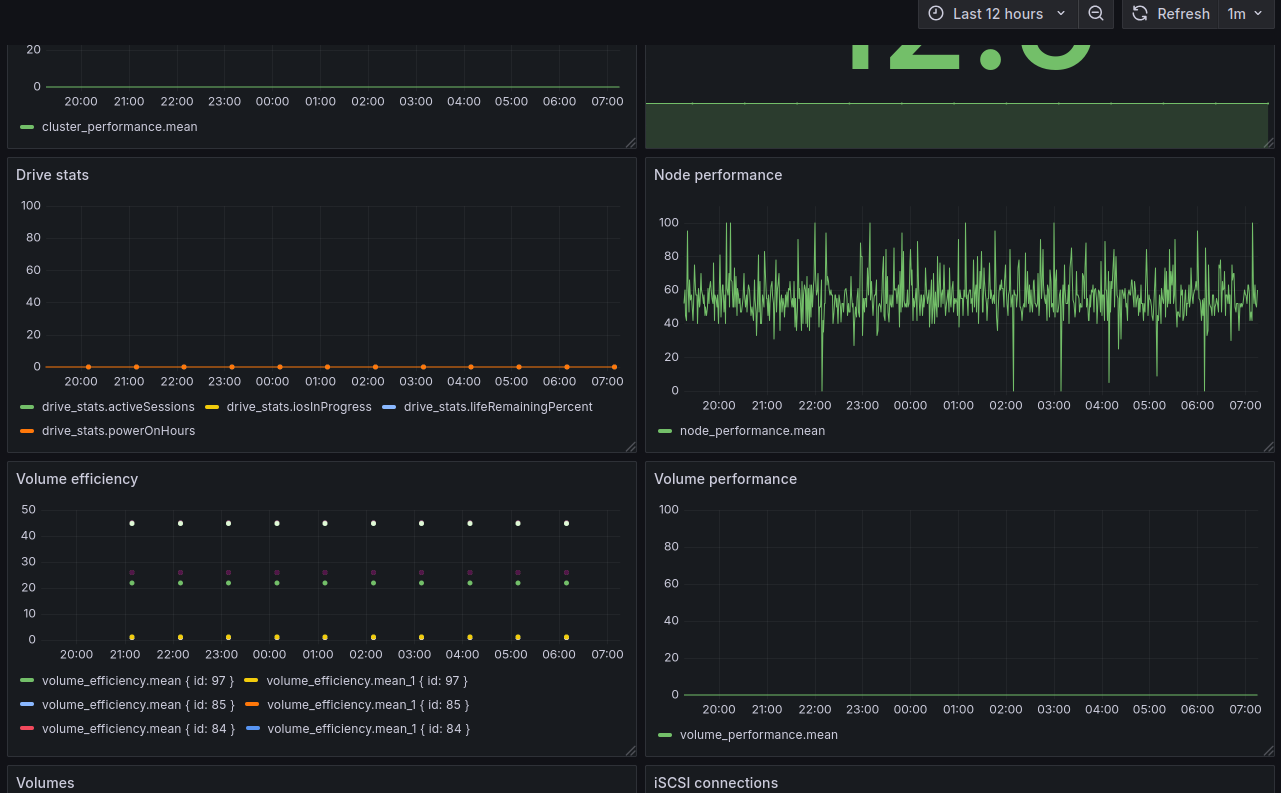
Completed:
- InfluxDB 1 replaced by InfluxDB 3 Core
- Tested with Grafana v12.0
- Better error handling (hopefully - I don't do tests)
- Documentation updates including a list of InfluxDB measurement fields and keys
To-do items:
Dockerfileupdates and testing
Once I'm done with Dockerfile I'll post the code to the Github repo.
When 2.0 was released I thought about doing more with Kubernetes and whatnot, but as I've said above - I've never gotten any feedback or help, so I assume no one uses SFC in Kubernetes, or existing Dockerfile and README.md are enough.
Queries
Even if you don't use Grafana, you can use SFC for reporting. For example, to get latest storage deduplication ratio for user "sean":
$ influxdb3 query -d sfc \
    'SELECT name, deduplication, time \
    FROM account_efficiency ORDER BY time DESC LIMIT 1' \
    --host https://192.168.1.146:8181
Result:
+------+---------------+-------------------------------+
| name | deduplication | time                          |
+------+---------------+-------------------------------+
| sean | 1.9           | 2025-06-18T06:09:04.957405167 |
+------+---------------+-------------------------------+
Alternatively, get a CSV report for use in Excel, for example.
$ influxdb3 query -d sfc --format csv \
    "SELECT time, deduplication \
    FROM account_efficiency \
    WHERE name='sean' ORDER BY time ASC"
time,deduplication
2025-06-17T12:13:29.952463962,1.9
2025-06-17T13:13:29.961647635,1.9
2025-06-17T14:13:29.958100991,1.9
2025-06-17T15:13:29.959858844,1.9
2025-06-17T19:09:04.952439641,1.9
2025-06-17T20:09:04.955352015,1.9
2025-06-17T21:09:04.949941921,1.9
2025-06-17T22:09:04.948299784,1.9
2025-06-17T23:09:04.952727462,1.9
2025-06-18T00:09:04.954448577,1.9
2025-06-18T01:09:04.949649938,1.9
2025-06-18T02:09:04.959137501,1.9
2025-06-18T03:09:04.959599778,1.9
2025-06-18T04:09:04.950650446,1.9
2025-06-18T05:09:04.947883764,1.9
2025-06-18T06:09:04.957405167,1.9
2025-06-18T07:09:04.954023409,1.9
Examples will be provided in documentation. In fact they've been available in existing SFC v2.0.0 documentation and one of the great things about InfluxDB 3 is the same InfluxQL from version 1 still works, so they're already available.
Summary
Folks who use SFC 2 and folks who didn't use SFC 2 because of InfluxDB 1 was "old" can use SFC with InfluxDB 3 (which will likely outlive all SolidFire clusters out there).
With tiering to S3 available now and retention and down-sampling likely coming soon, SFC 2.1 with InfluxDB eliminates the need for manual pruning without increasing the cost or complexity.
I haven't fully re-tested all of the SFC 2 features - for that, I'd need two SolidFire clusters with replication relationships, and I don't get the impression anyone out there needs it, so if something "advanced" turns out to not work, if you use and need that - create a Github issue once SFC 2.1.0 gets posted.