NetApp E-Series Performance Analyzer v3.5.3
Introduction
New minor version of E-Series Performance Analyzer is out.
This post is about the changes in v3.5.3 and some background information.
What's new and why
What's new is in the repo, but "why" is not. Since this information isn't suitable for change log, I'll provide it here.
Prometheus interface alerts
When Prometheus output was specified, EPA would export performance (not configuration) details via built-in Prometheus Exporter, as well as short failure count, but that doesn't contain interface details.
# HELP eseries_active_failures_total Number of active failures
# TYPE eseries_active_failures_total gauge
eseries_active_failures_total{failure_type="lostRedundancyDrive",object_ref="0100000058CE38EE2069E6210000000000000000",object_type="drive",sys_id="600A098000F63714000000005E79C17C",sys_name="box01"} 1.0
eseries_active_failures_total{failure_type="supportCruNoinput",object_ref="0A00000000000000000001000000000000000000",object_type="powerSupply",sys_id="600A098000F63714000000005E79C17C",sys_name="box01"} 1.0
eseries_active_failures_total{failure_type="hostRedundancyLost",object_ref="84000000600A098000E3C1B000302F0C650C2668",object_type="host",sys_id="600A098000F63714000000005E79C17C",sys_name="box01"} 1.0
# HELP eseries_interface_alert Interface alert status (1=down, 0=ok)
# TYPE eseries_interface_alert gauge
eseries_interface_alert{channel="1",interface_ref="2800070000000000000000000001000000000000",interface_type="mgmt_ethernet_wan0",sys_id="600A098000F63714000000005E79C17C",sys_name="box01"} 0.0
This last entry is what's v3.5.3 can output.
Management interface failures get detected and host-side should as well, although I've no JSON samples for other than iSCSI HICs. This screenshot shows how management and iSCSI HIC failures would get detected.
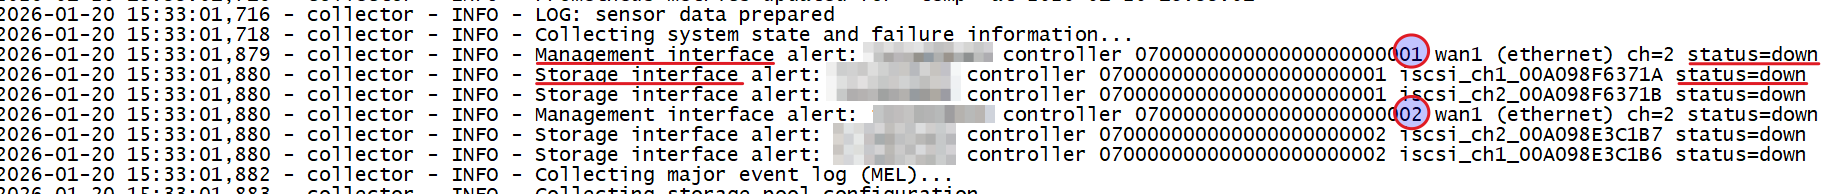
Let me know in EPA issues if it doesn't work for you (and provide your JSON output with --debug).
"Point-in-time" volume performance statistics
The other new thing is the option to poll non-averaged volume performance statistics. Why, and should you use it?
Here's why: NetApp Performance Analyzer always used "analysed-…" endpoints and I kept it as the "official" way of doing things. There's another reason we'll get to later. Here's how "analysed" volume perfomance (GET analysed-volume-statistics) stats work:
| Time | ReadOps |
|---|---|
| 15:01 PM | 138 |
| 15:02 PM | 174 |
All good, right? Well, you need to hold your breath for three minutes.
| Time | ReadOps |
|---|---|
| 15:01 PM | 138 |
| 15:02 PM | 174 |
| 15:03 PM | 174 |
Hmm… Keeep watching….
| Time | ReadOps |
|---|---|
| 15:01 PM | 138 |
| 15:02 PM | 174 |
| 15:03 PM | 174 |
| 15:04 PM | 174 |
| 15:05 PM | 174 |
| 15:06 PM | 174 |
| 15:07 PM | 122 |
If it looks very static, that's because it's a periodic average. It's updated every five minutes.
Considerations:
- NetApp EPA (not my fork) used that as well and I've kept it as I did not want to change this behavior
analysed-volume-statisticsstatistics are what users commonly expect from such statistics- Grafana charts often average last few values to smooth them out, so you still can get a smooth curve (it obfuscates individual values, of course)
- "Point-in-Time" probes would double volume statistics-gathering workload on API
- Users who collect statistics once every five minutes don't lose much fidelity with "analysed-"
But if you need or want precise figures, you may want to use volume-statistics (Point-in-Time).
Now in v3.5.3 you can use --realtime (non-cached, point-in-time sampling). That avoids static valus that analysed- API call gives. "Analysed" are still kept even when --realtime is used for users to be able to troubleshoot and compare. Use whichever you want.

Any downsides, you may ask? Yes, of course. "Realtime" volume performance API endpoint returns counter-style metrics.
EPA then caches responses to calculate the difference (current minus previous) and provides results as absolute figures. Prometheus counter example:
eseries_volume_realtime_throughput_bytes_per_second{direction="combined",sys_id="600A098000F63714000000005E79C17C",sys_name="box01",vol_name="ddp_r1_04"} 416904.5333333333
It handles counter wrapping and resets. The first iteration never produces any "realtime" metrics because they would have to be 0.
Who should use it? I guess if you capture on a shorter (1-5 minutes) interval and don't have > 100 volumes, it's fine to use this. If you're on longer intervals or have any volumes, keep an eye on time taken per interval, just make sure it finishes on time for next interval.
EPA's shortest supported interval is 60s and I haven't investigated what's the shortest interval "point in time" volume performance API updates. It might be less than 10 seconds, but due to EPA's shortest interval being 60s, that doesn't concern me much because 10s is way below what I'm interested in so no one will get caught fetching stale data.
What about "realtime" for other "analysed" performance statistics?
I'd say it's less relevant - and given the 60s minimum interval duration - and still doesn't give you second-level granularity, so I am not willing to double gathering of metrics and not in a hurry to make EPA code more complicated than it is. If you need precise granularity, you'd have to watch the hosts (E-Series storage clients).
Other minor things
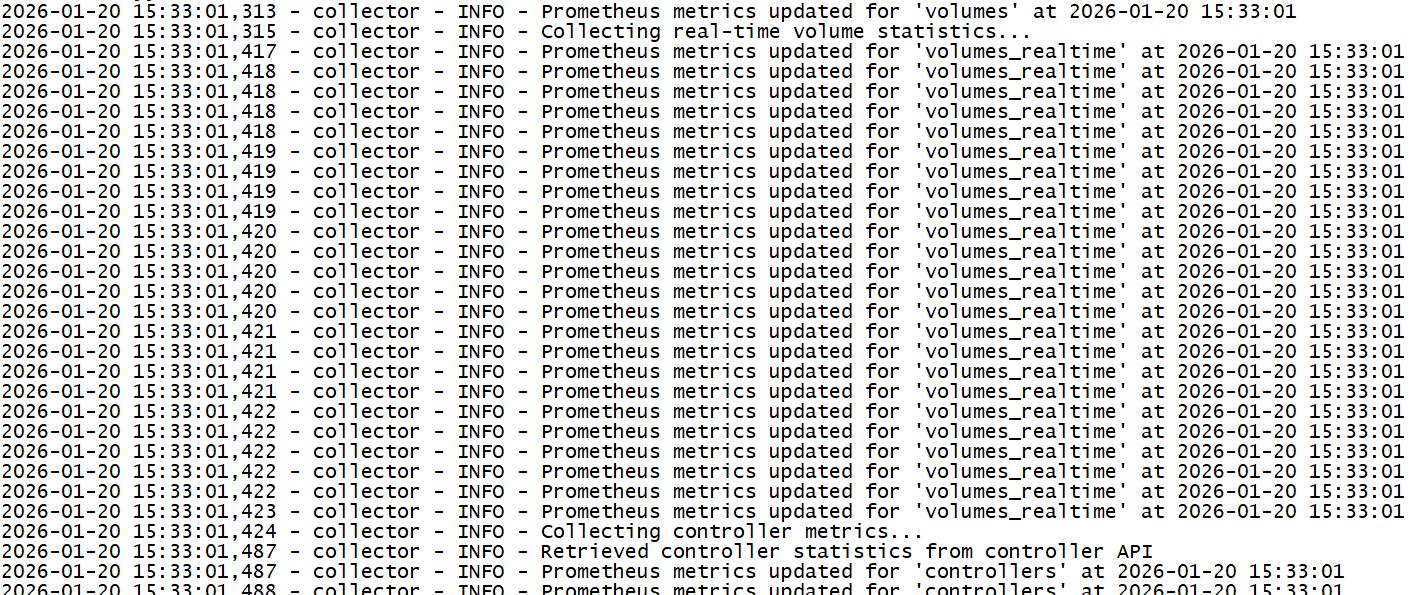
Some Python packages were updated, Prometheus exporter logging was enhanced and now EPA containers are generated in Github Container Registry, so it's WYSIWYG (from the source code to container images, with just Github as a single middleman).
Summary
EPA v3.5.3 adds minor improvements for users who need more up-to-date volume performance metrics or use EPA for interface and failure monitoring.
It appears NetApp Harvest intends to add E-Series support, so E-Series users will have another choice months from now. One monitoring tool is usually better than two, which is what happens now to users who use Harvest for ONTAP and EPA for E-Series. Being able to collapse these into one would be an improvement.
But EPA will remain much easier to use (in my opinion) because it's more flexible, more focused on SANtricity and still a single script. It's a very long script by now, but I'm keeping it as one file to make it easier to use.
E-Series SANtricity Collector is a complex application by comparison, and so is NetApp Harvest unless you run just the poller/Prometheus Exporter, but then you get the same thing (or worse, if the poller isn't as focused on E-Series as EPA) than with EPA.
EPA is also easier to fix and customize, so I don't intend to stop releasing EPA after Harvest adds E-Series support.
I'm very happy with InfluxDB 3 (used in E-Series SANtricity Collector), so I although InfluxDB 1 is still updated, I may upgrade EPA to use InfluxDB 3 for folks who want to save and analyze data and not just have it scraped by some centralized DB run by others.