Feed StorageGRID 12 data to Elasticsearch 9 indexes with Kompromise
Introduction
StorageGRID has two integrations with Elasticsearch. I blogged about them here: there's search and there's (indirect, via Logstash) logging.
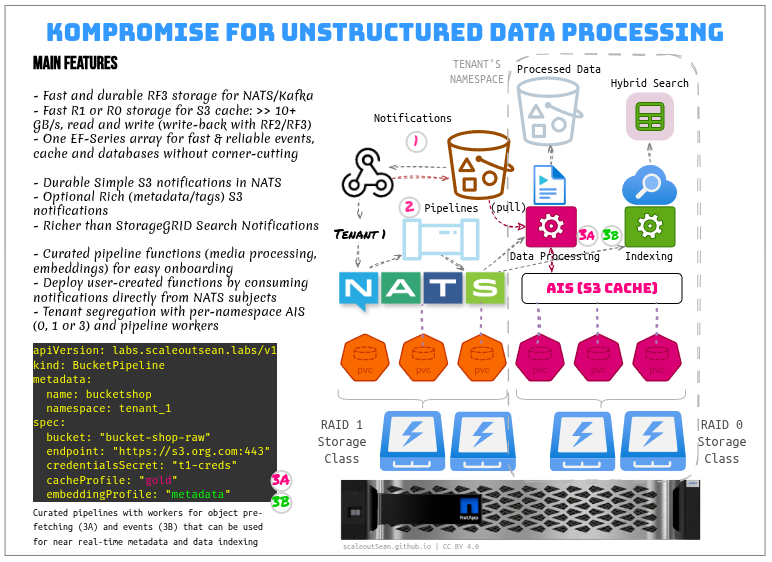
This post is about search. Let's see if we can integrate StorageGRID 12.1 and Elasticsearch 9 better using Kompromise.
This was already demonstrated in an early prototype of Kompromise called "Go NATS!" last year, but this is a more detailed version that are unlikely to change by the time I share Webhook binaries.
From Kompromise to Elasticsearch
As I wrote in the recent post on Kompromise Webhooks, there are simple and enhanced.
Here's an example of an index entry created from Enhanced Notifications in Kompromise:
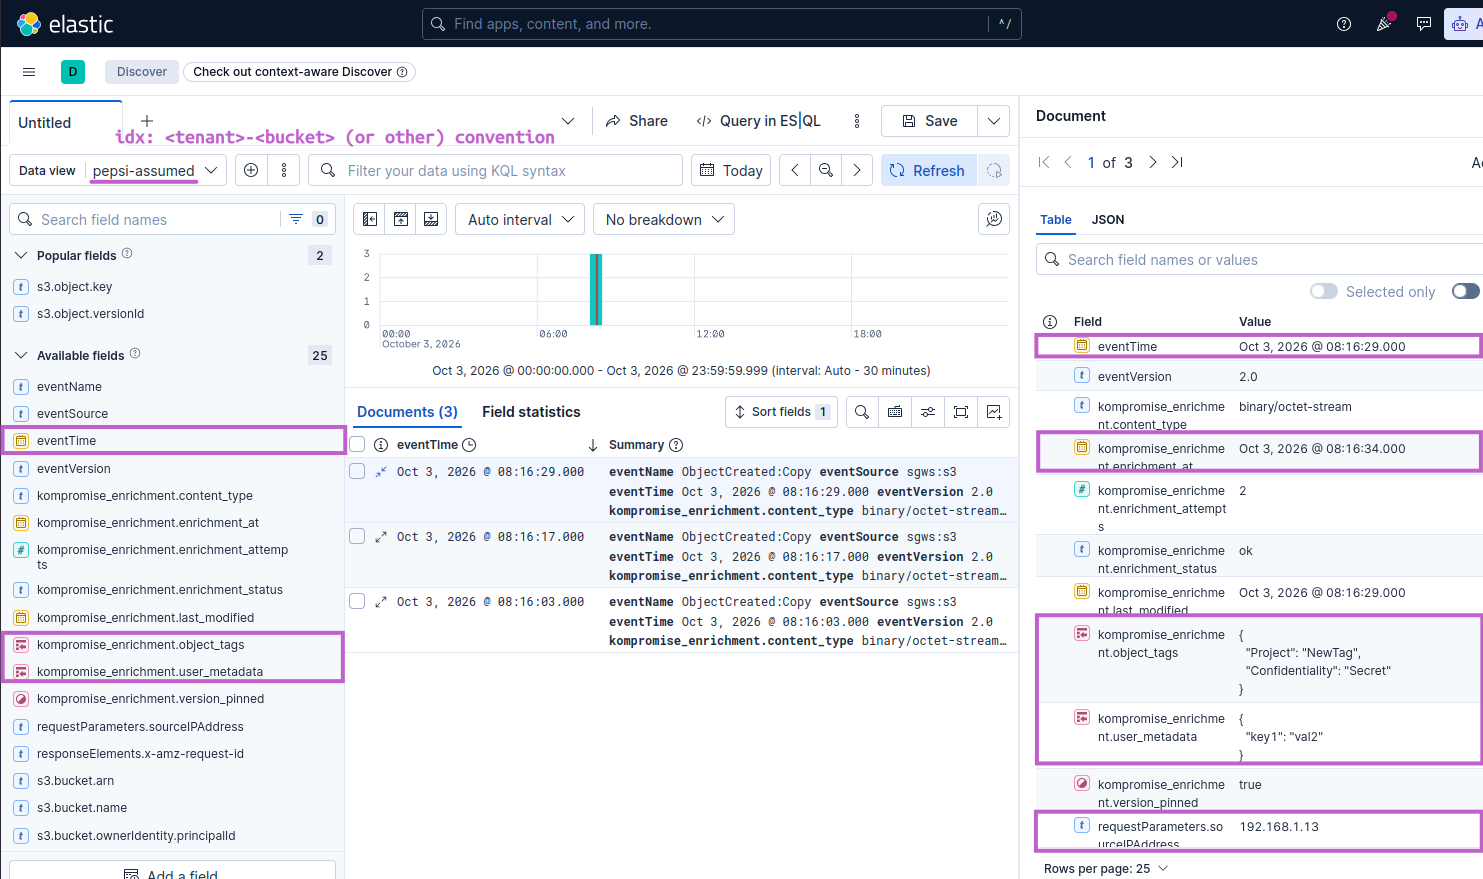
There are details such as date, tags, metadata and the source IP that created the object.
Simple notifications will have the usual (bare) details - nothing from kompromise.* above. Simple notifications are fine if you search for things like object names, prefixes and dates, but you probably realize that this is useless for most practical purposes (especially anything AI-related).
So:
- At the most basic level, you'd use Enhanced (aka "Rich") as in the screenshot above. At least, you can search by tags and metadata which you can't with "some other integrations"
- Sometimes, you'd just skip this approach altogether and use something that applies to this time and age, such as vector embeddings and full text search
We can do basic (Simple or Rich), we can do lexical, we can do vectors. And we can do all three kinds for the same bucket if we need to, as shown here (the assumed bucket).
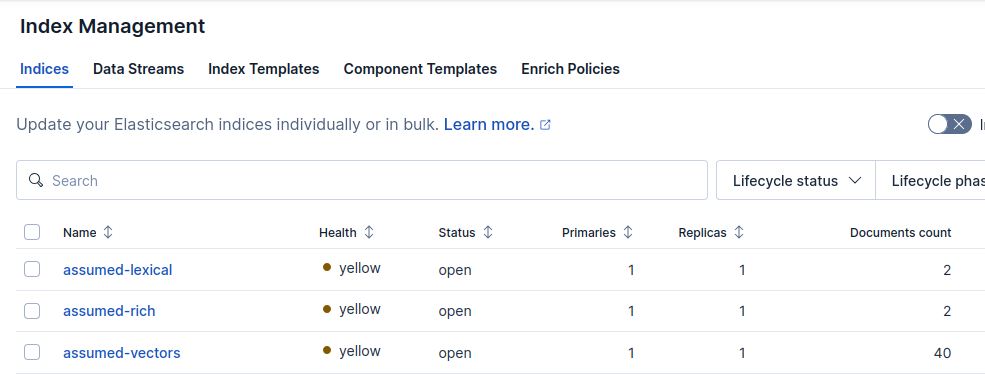
Search with Simple/Rich notifications
For basic search (that only stores data from Simple or Rich notifications), you don't have to do anything extra.
Pick 'em up from NATS and submit to Elasticsearch.
With Kompromise, indexing works better than StorageGRID's own Search Integration in 12.1 and that is reasonable, given that we use more resources to do it.
With Kompromise, Simple notifications are persisted in NATS queues and batched to Elasticsearch, so we consume IOPS on NATS (3x, at that) but spare Elasticsearch (also RF3, if you do it right) from being bombarded with 100 byte requests every few seconds - this is much better for Elasticsearch, especially if you pay for it! Rich Kompromise notifications may be lost in rare circumstances (heavy load on Kompromise or StorageGRID) but, as I explained elsewhere, if those are critical you can use Simple and create own jobs for reliable Rich that work off Simple.
Search also works better with Kompromise if you use Rich Notifications (tags, metadata are included).
Here's an example of default StorageGRID Search Integration entry (bucket versioning is off, unlike in the Kompromise Rich example above):
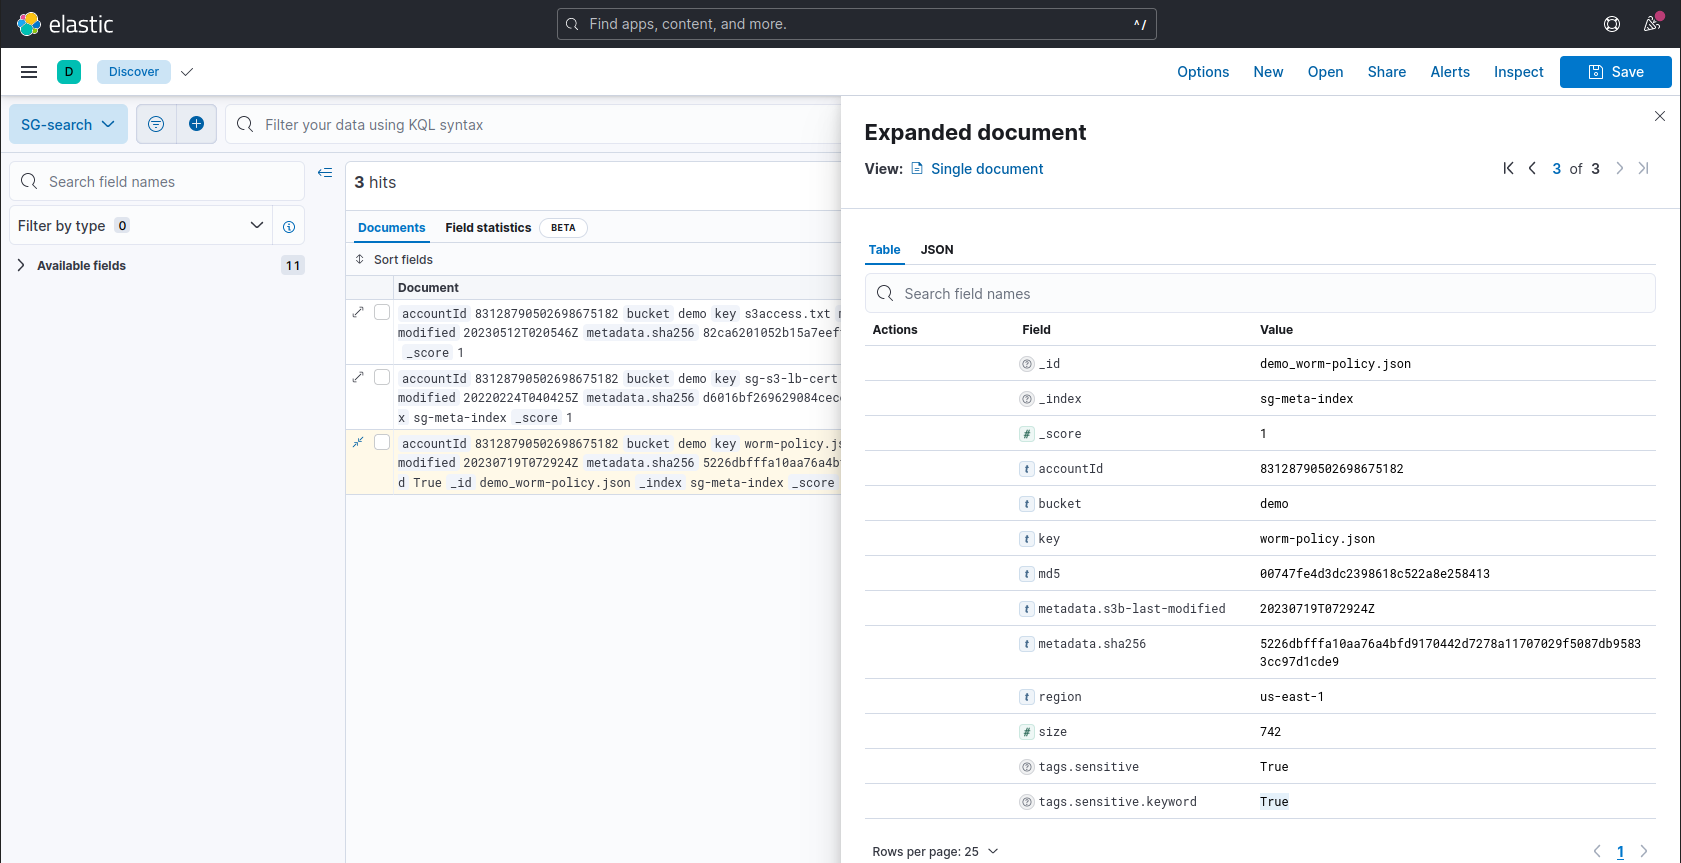
Let's just say this won't get your AI initiatives very far.
Full text search with Kompromise
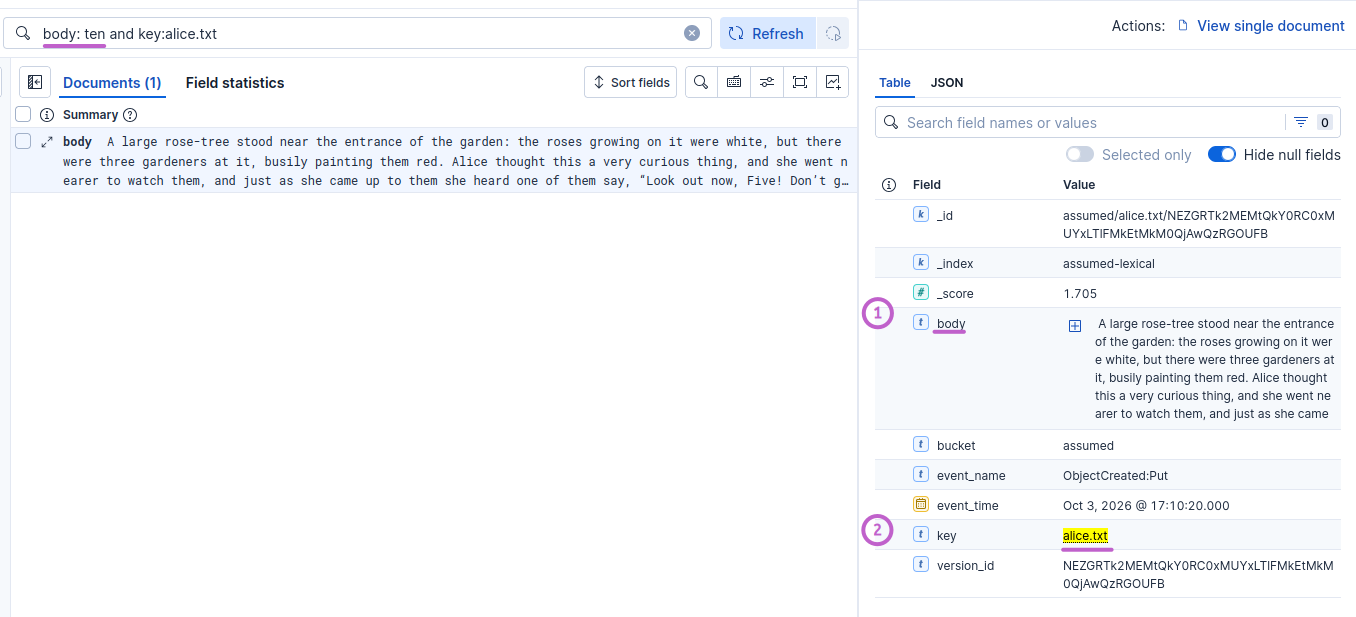
We need to read all object content and store it in body or similar index field.
This is impractical for huge documents which need to be broken down in shorter segments. For e-commerce product descriptions and even small to medium documents - it's fine.
I used the content from free books (Alice in Wonderland and Moby Dick) in my early testing. There were just a couple of KB each, so I did not need to prefetch to AIS.
Document conversion and OCR may be required before one can even begin, but we used text files (markdown, CSV, and similar formats would also work).
S3 access isn't a problem because this works out of tenant's Kubernetes namespace (which maps 1:1 to bucket name on StorageGRID). Our "worker" here needs GET access to read the object from the notification message.
Vector search with Kompromise
Here, too, we must read full content of the object.
The way that usually works is we "cut" an object in pieces ("chunks") and create embeddings for each. Then we store one or more embeddings under the S3 object's key in Elasticsearch.
Imagine that's a movie: 30 frames per second times 1,800 seconds. That's over 50,000 images.
We could probably run image analysis on just one compute node, but that would be much slower than if we did it on two or 12 Kubernetes workers.
That's where step 3A and the integrated AIS come in play: we can pre-fetch to cache (3A) and then compute. Or just compute (3B) using own client that connects to NATs or a curated function.
Here's a screenshot from the same "Alice in Wonderland" document, but with embeddings. This is the assume-vectors index.
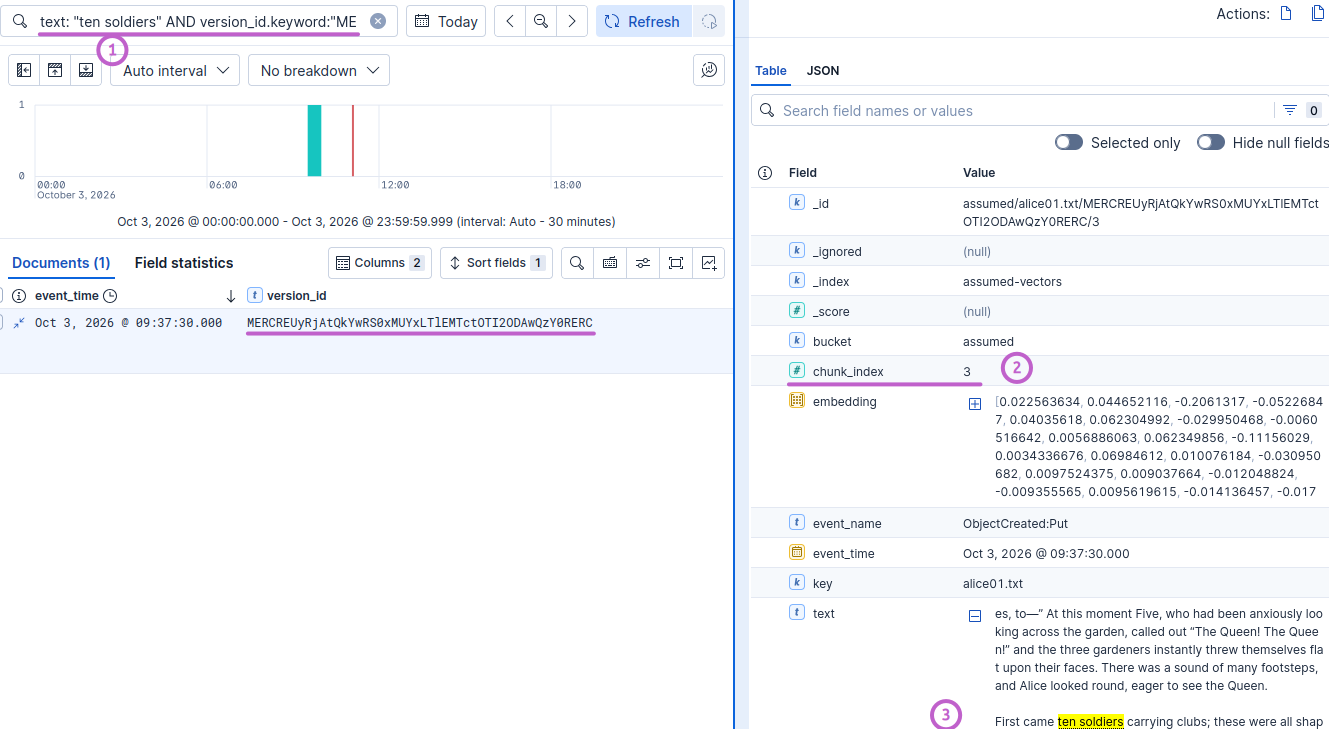
Unlike with Full Text Search, here I have a bunch of smaller chunks, each of which has a fraction of overall text, and a vector field for semantic search.
The query shows just one chunk, which is the chunk where "ten soldiers" are mentioned.
Community vs. commercial Elasticsearch
The free edition can't run own pipelines with vectors. This is why I create them on the client.
The commercial edition can run vectorization on Elasticsearch, using their own curated models which are very good.
Likewise, when searching on the free edition, I can't search embeddings for words. I compute questions into vectors on the client, and search for matching vectors on Elasticsearch. It works, but it's less convenient.
OpenSearch, on the other hand, is "free" but always has bugs and ends up frustrating me much more than the limitations in Elasticsearch'es Community Edition.
Search results
With lexical search, you type words. For an example, "ten soldiers". This does appear in the document and the entire the document gets found.
With embeddings, you look for stuff that may be found in multiple chunks. You can search with questions, but in the free version that doesn't work well because - mentioned above - you're not talking to a chatbot, you're comparing vectors.
The question was:
"Which of the two groups, gardeners or soldiers, was more numerous?"
Asking a question doesn't help at all because "which" doesn't help in content comparison, there's no mention of "ten soldiers", so results are likely to suck.
1. score=0.8049 assumed/alice01.txt#10
   d she put them into a large flower-pot that stood near. The three soldiers wandered about for a minute or two, looking for them, and then quietly marched off after the others.  "Are their heads off?" ...
2. score=0.7954 assumed/alice.txt#3
   es, to—" At this moment Five, who had been anxiously looking across the garden, called out "The Queen! The Queen!" and the three gardeners instantly threw themselves flat upon their faces. There was a...
Actually, this isn't bad, because chunk #3 is in fact one of two chunks that have the answer. But you don't get a chatbot answer, you get chunks whose contents match vectors from the query string you sent.
There are different techniques to do this better, but normally we'd work with agents or LLMs, so there's no need to try and turn this into a chatbot experience. It does work.
We can build one or both index types (lexical and semantic) or even something hybrid, depending what we need to achieve.
If you have the both kinds, you can do fancy searches or have an agent or LLM do that for you. So, our work on getting StorageGRID contents to agents and AIs has been completed!
- Documents get uploaded to a bucket
- Kompromise processes notifications and workers - that possibly require extra steps for conversion, extraction, normalization - store documents in Elasticsearch or OpenSearch (focus of this post, although we could use other indexers)
- Other steps: if documents are deleted, we need to decide what to do. Kompromise subjects wil have delete events, but you may or may not want to delete index documents - that depends on use case
- We need to make sure permissions on each index are open only to a tenant that has ownership of the bucket. But that's harder than it looks, because who would that be? The tenant administrator for the bucket? One of 100 tenant accounts? Who exactly?
Agents and LLMs
I'll leave this for another post related to Kompromise, but I've written about this before and created some examples with indexes on S3. This is the same thing except indexes are stored on block devices (e.g EF-Series) and tiered to S3 only later.
But let's see what we expect to happen later:
- We have one or two indexes
- We have an chatbot or agent that can use these in many different ways
- Now we, or agents that work with agents that have access to these indexes, can ask questions, not just enter words or throw vectors at it
YMMV, as they say. Earlier, we've established there were ten soldiers. At least, that's what I thought.
Example answer from approach A:
[answer] The story mentions ten soldiers carrying clubs in passages [3] and [4], which describe them as part of a procession. While passages [1] and [2] reference three soldiers, these are likely part of the same group of ten, as the narrative context suggests a cohesive scene. Therefore, the total number of soldiers in the story is ten.
Example answer from approach B:
[answer] The story mentions three soldiers in passages [3] and [4], and ten soldiers in passage [5]. These groups are distinct, as the ten soldiers are part of a procession during the Queen's arrival, while the three soldiers are part of the court. Thus, the total number of soldiers is 3 + 10 = 13.
That's pretty intriguing. But it's also not our problem: we are in charge of making sure they have data to work with.
Chunk details ([3] and [4]) and document URIs is what you'd get as URLs to the sources - the same as in my other RAG-related posts.
Comparison vs…
Kompromise isn't a product and if it gets published it will be distributed as (binary) freeware, so it shouldn't be compared with shipping or supported products.
As of now, your choices are limited and you have to build own integrations. Maybe Komprise can work well with StorageGRID notifications, but their documentation isn't detailed (or publicly available).
Just two-three days ago Blocks & Files mentioned NetApp partnered with Diskover. I don't know how Diskover works with StorageGRID, but presumably it will, and I expect it will work the same way Kompromise does.
There are data migration products such as Datadobi, which support StorageGRID. I think they may subscribe to notifications as that would be helpful in migrations, but I don't know if any of them do it.
Finally, earlier this week NetApp also announced next version of AIDE would support StorageGRID. As of October 4, there is this page which indicates that indexes are built using brute-force listing (full ObjectListv2 every time you update), so it may not be directly comparable to Kompromise.
But indeed, if we have TBs of data that's already in a bucket, how to index it?
- Please do not worry. It's just one CLI command with AWS CLI or MinIO client. You can output result to a file and loop through it to get the data you need
- If you need to create embeddings or lexical index, it may be worth automating with Kompromise or other workflow
But wait, why even use Notifications when we can simply re-index buckets?
- You can't reindex an entire bucket every minute, but you can receive Notifications of new objects every second
- Brute-force searching doesn't work at scale. Imagine re-listing all objects a cross hundreds of TB sized buckets… I don't know if that's what others do or not, but I do know that's unlikely to work well
- There's no substitute for Notifications. It doesn't matter how you get 'em Webhooks or Kafka, everyone gets the same information. Kompromise Webhooks won't have less information than anyone else, so I expect them to remain the least dirty shirt in the closet. You can supplement Notifications with full re-scan once a week to pick objects you missed and maybe reconcile and Kompromise can do that as well
As far as getting the full list (and building a search index from that content) of a bucket is concerned, we already have a free solution for that: Snapshot Leases with sg-cosi:
- You create a Snapshot Lease using my StorageGRID COSI driver, let's say it's a 48 hour lease
- That gives you 48 hours (can be extended) to access it from anywhere it's accessible from using ephemeral S3 keys
- Snapshot Leases function in my COSI driver was created for bucket backup workflows, but you can use it to run ListObjectsv2 for 36-hours if you like
- Then, you can send those results to any, or several, places
Conclusion
In 2026, keeping your data out of reach for agents is almost as bad as keeping it on tapes.
Kompromise makes StorageGRID-parked data more valuable because with it, you and your agents can actually find your stuff.
I mention in every Kompromise post: the Webhook is the only new part here, while the rest is off the shelf software, but I perhaps shouldn't, because much of commercial software is not any better.
Today's post doesn't include AIS, but it does show that simply with the Webhook and per-tenant NATS queues, I can easily deliver any search integration I need - including heavy media processing - without spending days on reinventing the wheel.
While the scripts to used to populate Elasticsearch indexes aren't part of Kompromise, I may add their key parts to the repo where Kompromise Webhook is expected to appear. These are out of scope (downstream from Kompromise) and everyone does things slightly differently, so I'd rather let everyone do what they like with StorageGRID events.